LLMs
The specifics of working with language models: model comparisons on cost and latency, when RAG beats fine-tuning, and how to stop the token bill from running away as you scale.
Typed AI vs generative: when to use each
LLMs generate free text. Jev returns typed values with probability. For extraction, classification or scoring, the difference matters.
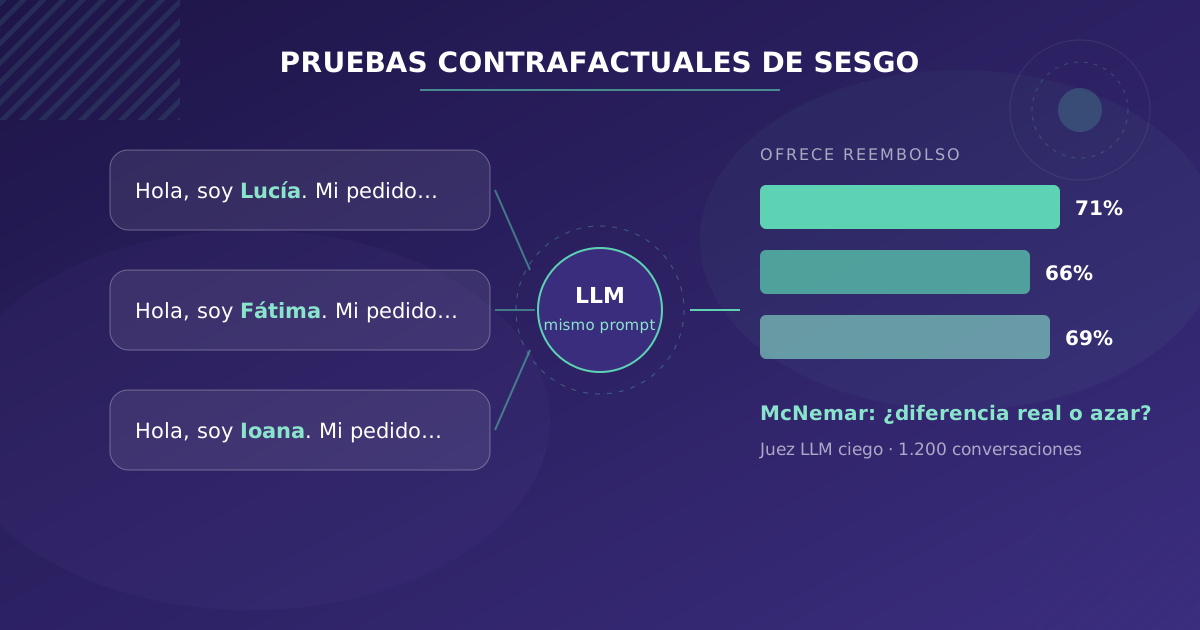
How to audit chatbot bias with counterfactual tests
How to measure whether your chatbot treats two users differently when only their name, age or origin changes: test pairs, a blind LLM judge and statistics.
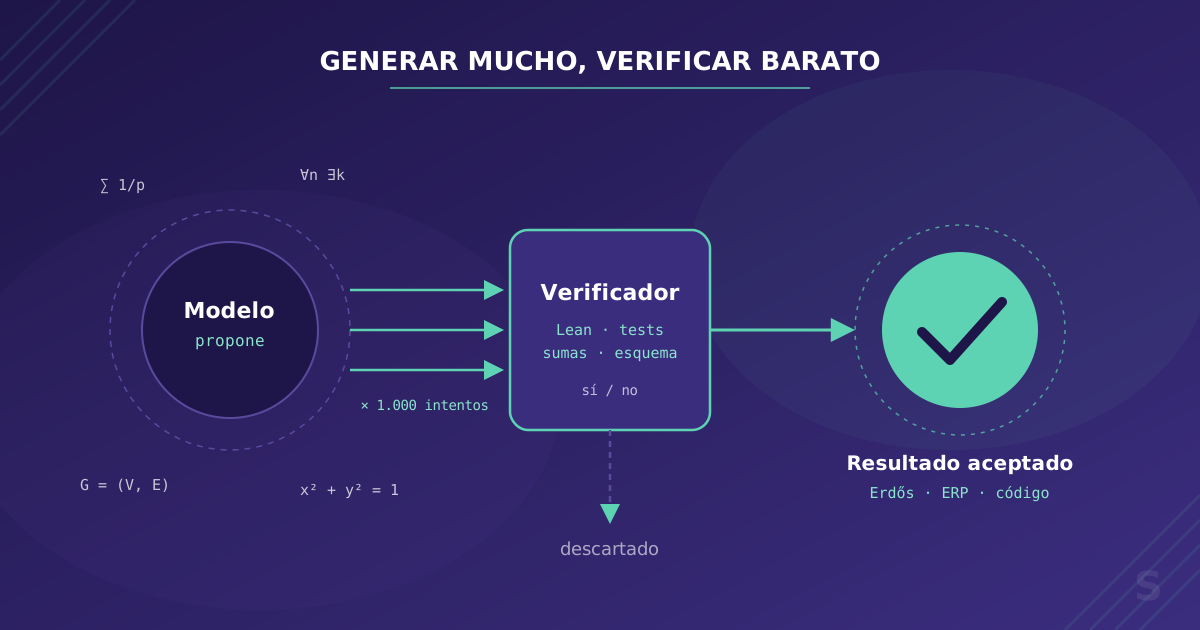
AI is solving open math problems: what a business can copy from the method
Erdős, Navier-Stokes, AlphaEvolve: what AI solved in mathematics in 2026, why it worked and how to apply the same pattern to your company's software.
Prompt Engineering Is Dead. Here's What Replaced It
Why prompt engineering as a standalone skill is dead and what's replacing it: structured outputs, tool use, and context engineering.
LLM-as-Judge: How to Auto-Evaluate AI Output Quality in Production
Practical guide to using LLMs as quality evaluators in production: frameworks, metrics, code examples, and common pitfalls.

From a mega-prompt to a pipeline: how we took an AI process from 58s to 14s
Splitting a monolithic prompt into specialised steps cut latency from 58s to 14s. Architecture, real measurements and prompting examples.

How to Build a Custom AI Agent with LLM for Customer Service
Technical guide to building an AI agent with LLM models that delivers personalized customer service, overcoming the limitations of generic chatbots.
What Running LLMs in Production Actually Costs (With Numbers)
A real breakdown of LLM production costs: tokens, infrastructure, latency, and optimization strategies with current 2025-2026 pricing data.

RAG vs Fine-tuning: When to Use Each in 2026
Choosing between RAG and fine-tuning for enterprise AI. Cost, performance comparison and decision framework 2026.
Tell us your challenge. We'll propose a solution.
No commitment. We reply within 24 hours, and within 48 hours you have a proposal with scope, timeline and budget. No fine print.